Research briefing · Updated 17 September 2026
AI search searches the web when fresh, specific or externally verifiable information is needed — but not every AI answer triggers retrieval
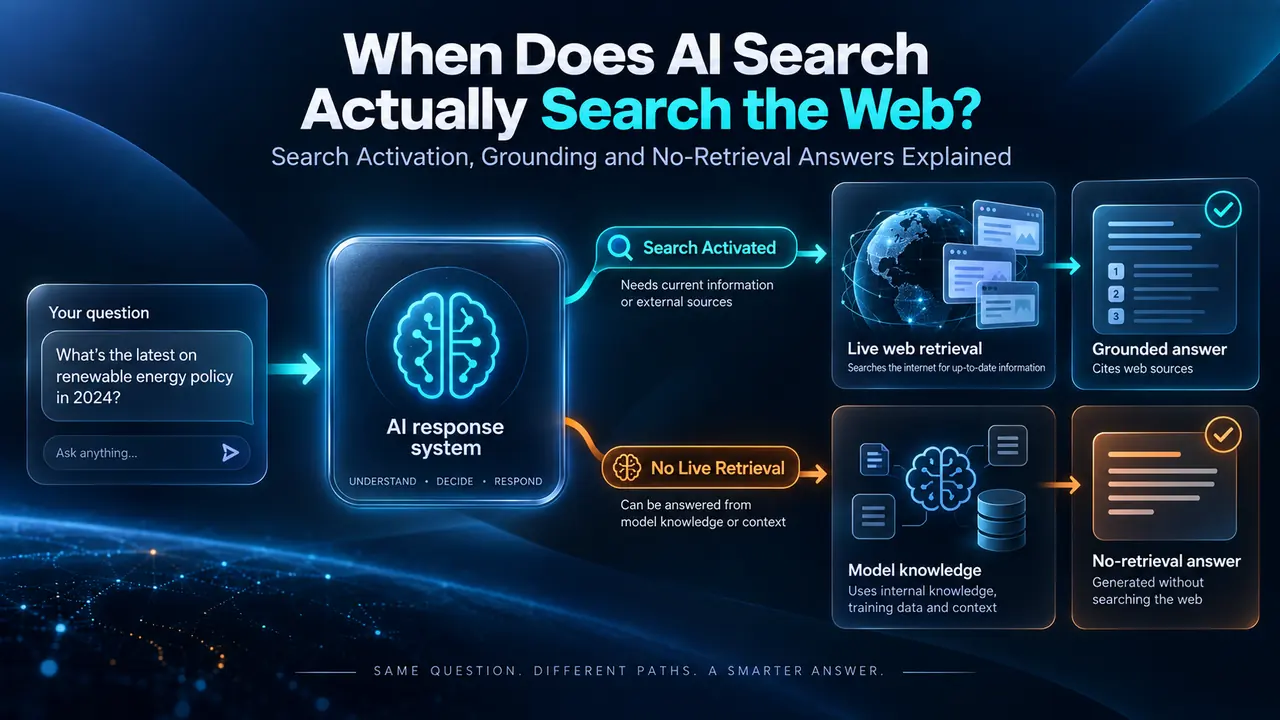
AI search does not automatically search the live web for every prompt. In retrieval-capable systems, the model or product may decide that web search will improve the answer, may be operating in a search-first mode that retrieves by design, or may answer from model knowledge, attached context or other connected data without making a web request. The practical consequence for Generative Engine Optimisation is simple: a page can only compete for retrieval, source selection and citation when the system actually enters a retrieval pathway.
That distinction is now documented directly by major platforms. OpenAI says ChatGPT can choose to search based on what the user asks; Anthropic says Claude determines whether web search would improve accuracy; Google’s Gemini Search grounding decides whether search is needed and can generate one or multiple queries; Microsoft Copilot parses prompts for terms where web information would improve the response; and Google AI Mode is explicitly built around query fan-out across Search and other data sources. OpenAI Anthropic Google Gemini API Microsoft Learn Google Search Help
TL;DR: When does AI search actually search the web?
AI systems search the web when the product is configured for retrieval and the query benefits from current, niche, location-sensitive, source-backed or otherwise external information. They may not search when the answer can be produced from model training, supplied files, conversation context, enterprise data or cached/indexed knowledge. Search activation, retrieval, grounding, citation and answer generation are separate stages — and a citation is evidence of a source being exposed to the answer, not proof that every sentence came from that source.
Search activation
Decision or product state that causes a web search/retrieval tool to run.
Grounding
Using retrieved or supplied external information to anchor an answer.
No-retrieval answer
An answer generated without a live web retrieval step.
What actually happens when an AI answer can search the web?
A retrieval-capable AI answer normally passes through several distinct decisions: interpret the prompt, decide whether external information is needed, formulate one or more searches, retrieve candidate sources, select evidence, and then synthesise the answer. These stages can be collapsed or expanded depending on the product, and some products are search-native while others only invoke search conditionally.
This matters because the phrase “AI search” hides multiple architectures. A model may have a web-search tool available but not invoke it. A search product may retrieve every time. A workplace assistant may ground on private files instead of the public web. An answer can also combine internal model knowledge with external evidence.
| Stage | What the system is deciding | Can a website influence this stage? | Typical evidence visible to the user |
|---|---|---|---|
| 1. Prompt interpretation | What is the user actually asking, including entities, freshness and task intent? | Indirectly — through entity clarity, topical relevance and language that matches the information need. | Usually none. |
| 2. Search activation | Would web retrieval materially improve the answer, or is retrieval already mandatory in this mode? | Mostly indirectly. The query and product mode dominate. | A search indicator, tool call, source panel or citations may appear. |
| 3. Query generation / fan-out | Which keywords, entities, subtopics or follow-up searches should be issued? | Yes, if the page aligns with the generated query space and entity relationships. | Some products expose generated search queries; many do not. |
| 4. Retrieval and reranking | Which pages or data sources are candidates, and which are most relevant? | Yes — crawlability, relevance, structure, freshness and source quality matter here. | Often invisible; citations show only a subset of what may have been fetched. |
| 5. Grounding and source selection | Which retrieved evidence should anchor claims in the answer? | Yes — extractable facts, provenance, support quality and source trust matter. | Citations or source links, where the product exposes them. |
| 6. Synthesis | How should evidence and model knowledge be combined into a coherent response? | Indirectly — through clear, self-contained, faithful passages that can be reused safely. | The final answer text. |
Mobile note: swipe or scroll horizontally to view the full table.
What is search activation in AI search?
Search activation is the point at which an AI system decides to invoke a search or retrieval mechanism, or enters a product mode in which retrieval is already part of the answer pipeline. It comes before retrieval, citation and synthesis, so it is an upstream gate that determines whether public web pages can participate at all. Google Search Grounding Anthropic Web Search Microsoft Learn
OpenAI describes ChatGPT Search as something ChatGPT can choose to use “based on what you ask,” while users can also invoke search directly. Anthropic says Claude decides whether web search would help when a request benefits from up-to-date or specialised information. Google’s Gemini API documentation similarly states that, with Google Search grounding enabled, the model analyses the prompt and searches “if needed.” Microsoft says Copilot identifies terms where web information would improve answer quality and sends a generated query to Bing. OpenAI Search Anthropic Web Search Gemini Grounding Microsoft Web Search
What kinds of prompts are most likely to trigger web search?
Prompts are most likely to trigger retrieval when they depend on information that can change, is niche, needs verification, requires external sources or cannot be safely answered from model knowledge alone. Exact activation rules are proprietary and can change by model, mode, account and product setting, so these should be treated as strong operational patterns rather than universal thresholds. OpenAI Search Anthropic Web Search Google Search Grounding
| Activation signal | Why retrieval becomes useful | Example |
|---|---|---|
| Freshness / recency | The answer may have changed since model training or the last index update. | “What happened in the UK AI search market this week?” |
| Current prices, availability or schedules | Values are volatile and time-sensitive. | “What is the current price and availability of this product?” |
| News or newly published research | The required evidence may post-date the model’s built-in knowledge. | “What did the September 2026 paper conclude?” |
| Niche or long-tail facts | The model may not contain enough reliable parametric knowledge. | “What does this specialist trade body say about X?” |
| Source-demanding prompts | The user explicitly asks for links, evidence, quotes or citations. | “Find the primary source and cite it.” |
| Local or location-dependent questions | Results depend on place and current business information. | “Which firms near me provide X?” |
| High-complexity research | Multiple sources or subtopics are needed for synthesis. | “Compare the evidence across five competing methods.” |
| Explicit search instruction | The user directly tells the system to browse or search. | “Search the web before answering.” |
Mobile note: swipe or scroll horizontally to view the full table.
What does current research show about how often web-enabled AI systems answer without searching?
A 2026 Cambridge Data & Policy study based on roughly 14,000 real-world LMArena conversation logs found explicit no-search behaviour in a material share of responses even for web-enabled systems. In that dataset, 34% of Google Gemini responses and 24% of OpenAI GPT-4o responses were generated without explicitly fetching online content. Those figures are observational and model/version specific; they are not universal rates for today’s products. Cambridge Data & Policy
Observed explicit no-search share
Google Gemini — 34%
OpenAI GPT-4o — 24%
■ Teal = Google Gemini ■ Orange = OpenAI GPT-4o
Mobile note: swipe or scroll horizontally to view the full chart. Source: Cambridge Data & Policy
| System in the study | Explicit no-search share | Interpretation |
|---|---|---|
| Google Gemini | 34% | About one-third of logged responses did not explicitly fetch online content in the study dataset. |
| OpenAI GPT-4o | 24% | About one-quarter did not explicitly fetch online content in the study dataset. |
Mobile note: swipe or scroll horizontally to view the full table.
Do ChatGPT, Google AI Mode, Gemini, Claude, Microsoft Copilot and Perplexity search the web in the same way?
No. The major products differ in whether retrieval is conditional, search-native, user-controlled, mode-dependent or connected to other data sources. Treating them as one retrieval system is a major analytical error in GEO testing. OpenAI Google AI Mode Anthropic Microsoft Perplexity
| Platform / experience | Is public-web retrieval conditional or intrinsic? | Documented behaviour | GEO implication |
|---|---|---|---|
| ChatGPT Search | Conditional in general ChatGPT; users can also invoke search directly. | OpenAI says ChatGPT chooses to search based on what the user asks; answers using search can include citations. | A brand can be strong in the model’s no-search answer yet absent from search citations, or vice versa. Test both states. |
| Google AI Mode | Search-native. | Google says AI Mode uses query fan-out, dividing a question into subtopics and searching them simultaneously across multiple data sources. | Optimise for families of subqueries and entity relationships, not just one visible prompt. |
| Gemini with Google Search grounding | Conditional once the search tool is enabled. | Gemini analyses the prompt and, if needed, automatically generates one or more Google searches before producing a grounded response. | Search activation and source selection should be tested separately. |
| Claude Web Search | Conditional when web search is available/enabled. | Anthropic says Claude decides whether search would help for up-to-date or specialised information, then generates a targeted query and cites sources. | No-search and search-enabled Claude runs can produce different source sets and brand visibility. |
| Microsoft Copilot / Copilot Chat | Conditional and admin/user controllable in supported experiences. | Copilot parses the prompt for terms where web information would improve the answer and sends generated queries to Bing when web search is enabled. | Generated Bing queries can differ from the user’s wording; content must cover the underlying concepts. |
| Perplexity Standard / Pro Search | Retrieval-led search product. | Perplexity describes Standard Search as quick search with basic citations and Pro Search as conducting multiple searches, crawling sources and synthesising cited answers. | Source retrieval and citation are central to the product experience, but not every retrieved page is necessarily cited. |
Mobile note: swipe or scroll horizontally to view the full table.
The platform documentation is unusually consistent on one point: retrieval is a tool or pipeline stage, not the same thing as the language model itself. That is why a model can answer coherently without touching the web and why a retrieval-enabled answer can incorporate both fetched evidence and pre-existing model knowledge.
What does “grounding” mean in AI search?
Grounding means anchoring an AI response in external information that the system has retrieved or been given, such as web pages, files, enterprise data or a search index. Grounding can improve freshness, traceability and factual support, but it does not guarantee that every claim is correct or that every fetched source will be cited. Google Search Grounding Microsoft Learn
Google describes Search grounding as connecting Gemini to real-time web content so it can provide answers beyond its knowledge cutoff and return citations. Microsoft defines grounding more broadly as connecting an answer to real information such as work data, the web or attached content. OpenAI distinguishes ordinary model knowledge from answers produced using Search or Deep Research. Google grounding Microsoft grounding OpenAI truthfulness guide
Does grounding guarantee accuracy?
No. Grounding reduces one important source of error — reliance only on model memory — but the system can still retrieve weak sources, misread context, omit relevant evidence or synthesise a claim more strongly than the source supports. Google’s own AI Mode help page warns that the system can misinterpret web content or miss context, while OpenAI advises users to verify that citations actually support the answer. Google AI Mode OpenAI Search
This is why Generative Engine Optimisation should optimise for citation fidelity, not merely citation presence: the source should genuinely support the claim the AI is likely to extract. That is also consistent with NeuralAdX Ltd’s September 2026 methodology update, which separates citation visibility from source support, answer absorption and trustworthiness.
What is a no-retrieval AI answer?
A no-retrieval answer is generated without a live public-web search or external retrieval step for that response. The answer can still be fluent and factually correct because the model draws on patterns encoded during training, conversation context or supplied material, but it is not freshly grounded in live web evidence. OpenAI Web Search Anthropic Web Search
Why would an AI system answer without searching?
It may decide that the question is stable, common, creative, conversational or already answerable from the available context, making a web call unnecessary. Other reasons include disabled web access, account or admin settings, latency/cost trade-offs, safety constraints, unavailable sources, tool failure, or a product mode that does not permit search. Anthropic Web Search Google Search Grounding Microsoft Learn
| No-retrieval route | What the answer uses | Example | What a website can do |
|---|---|---|---|
| Model knowledge | Information learned during training. | Definition of a stable concept. | Build durable entity and topic presence over time, but there is no live retrieval opportunity in that response. |
| Conversation context | Earlier messages in the same thread. | “Summarise what we agreed above.” | No public-web competition occurs unless search is activated separately. |
| Uploaded / attached content | Documents, images or links supplied directly by the user. | “Explain this PDF.” | The attached source may dominate the answer regardless of public rankings. |
| Enterprise/private grounding | Work files, email, CRM or other connected data. | “What is the latest status of Project X?” | Public GEO may be irrelevant to that answer unless web data is also used. |
| Cached or indexed retrieval | A platform may use indexed/cached material rather than a live crawl of the page at answer time. | Workspace or search-index scenarios. | Freshness depends on recrawl/reindex cadence, not just page publication time. |
Mobile note: swipe or scroll horizontally to view the full table.
Does a citation prove that AI search retrieved that page — and does retrieval guarantee a citation?
A visible citation is strong evidence that a source participated in the answer pipeline, but retrieval and citation are not equivalent: a system can retrieve pages it does not cite, and a citation does not prove that every nearby sentence was derived faithfully from that page. Citation is therefore a downstream exposure signal, not a complete record of everything the system searched, fetched or considered. Cambridge Data & Policy OpenAI Search
The 2026 Cambridge study on the “attribution gap” found that Perplexity Sonar visited roughly 10 relevant pages per query but cited only three to four on average, illustrating that source consumption can exceed visible source credit. Cambridge study
Illustrative Perplexity Sonar attribution gap using the study midpoint
■ Teal = visibly cited ■ Slate = retrieved/visited but not visibly cited
Mobile note: swipe or scroll horizontally to view the full stacked bar. The 35/65 split is an editorial visualisation using 3.5 as the midpoint of the study’s “three to four” cited pages out of approximately 10 visited pages; it is not a platform-wide citation rate.
| Component | Approximate pages per query in the cited observation | Midpoint visual share |
|---|---|---|
| Visibly cited | 3–4 | ≈35% using 3.5/10 |
| Visited/relevant but not visibly cited | ≈6–7 | ≈65% by remainder |
Mobile note: swipe or scroll horizontally to view the full table.
What is query fan-out, and why does it change what “searching the web” means?
Query fan-out means decomposing one user question into multiple related searches that cover subtopics, entities, constraints or evidence needs before synthesising a final answer. It means the visible prompt is not necessarily the only query your content must match. Google Search Help Google AI Mode
Google explicitly says AI Mode breaks a question into subtopics and searches for each one simultaneously. Microsoft similarly says Copilot sends a generated search query that can differ from the user’s original prompt. Gemini grounding can automatically generate one or multiple searches. These behaviours shift GEO from “rank for this exact prompt” toward “be retrievable across the likely query family.” Google AI Mode Microsoft Copilot Gemini API
| Visible user question | Possible fan-out / generated-query dimensions | Content that becomes retrievable |
|---|---|---|
| “Who are the best GEO specialists in the UK?” | UK GEO companies; evidence of GEO performance; AI citation benchmarks; client/service scope; recent proof. | Provider pages, benchmark pages, proof assets, methodology and third-party mentions. |
| “Does GEO actually work?” | Academic GEO research; live experiments; AI visibility metrics; citation evidence; limitations. | Research summaries, experimental evidence, benchmark methodology and caveats. |
| “How do I get cited in ChatGPT?” | ChatGPT search retrieval; crawlability; topical relevance; source quality; extractability; citations. | Technical guidance, authoritative evidence blocks, platform documentation and live testing. |
Mobile note: swipe or scroll horizontally to view the full table.
How large and search-intensive has Google AI Mode become by 2026?
Google reported in May 2026 that AI Mode had surpassed one billion monthly users globally and that AI Mode queries had more than doubled every quarter since launch. Google also reported that 75% of people in one company-cited survey said AI Mode helped them make faster, more confident decisions. These figures are Google-reported product metrics, not independent market-share estimates. Google I/O 2026 Google Ads & Commerce
Two current Google-reported AI Mode signals
Monthly-user scale marker — >1 billion users (normalised to a full 100% reference bar)
Surveyed users reporting faster, more confident decisions — 75%
■ Teal = reported monthly-user scale ■ Orange = reported survey percentage
Mobile note: swipe or scroll horizontally to view the full chart. The first bar is a normalised scale marker because a user count is not itself a percentage; the underlying data are stated explicitly below.
| Google-reported metric | Value | Date / limitation |
|---|---|---|
| AI Mode monthly users | More than 1 billion globally | Google, 19 May 2026; company-reported usage figure. |
| AI Mode query growth | More than doubled every quarter since launch | Google, 19 May 2026; growth statement, no raw query counts published in the cited post. |
| People reporting faster, more confident decisions using AI Mode | 75% | Google-cited survey figure in a May 2026 advertising post; survey context should not be treated as universal user behaviour. |
Mobile note: swipe or scroll horizontally to view the full table.
What does search activation mean for Generative Engine Optimisation?
Generative Engine Optimisation must optimise for the entire retrieval-to-answer pipeline, not only the final citation. If search never activates, public-web citation optimisation cannot affect that specific answer. If search does activate, the page still has to be crawlable, retrieved, reranked, trusted, selected and used faithfully. NeuralAdX Ltd methodology Google Search Grounding
For NeuralAdX Ltd, Generative Engine Optimisation is the parent specialist discipline: AI SEO, AEO, LLMO and platform-specific “ChatGPT optimisation” or “Google AI Mode optimisation” are useful search-language labels, but the operational work is broader. It includes AI retrieval testing, crawlability, semantic relevance, citation readiness, entity clarity, prompt coverage, trust signals, source selection, structured machine readability and repeated visibility measurement.
Which GEO priorities become most important once retrieval behaviour is understood?
| Priority | Why it matters in the activation → retrieval → grounding pipeline | Practical implementation |
|---|---|---|
| Step 0: AI crawler access & technical eligibility | A page cannot reliably enter retrieval if relevant systems cannot obtain usable content. | Check robots controls, CDN/WAF behaviour, HTTP delivery, discoverability, canonicalisation and accessible HTML. |
| Semantic relevance & retrieval | Generated search queries may differ from the user’s wording. | Cover entities, subtopics, synonyms, constraints and real decision criteria around the search intent. |
| Completeness & extractability | Retrieved content still has to supply usable evidence containers. | Use direct answers, definitions, tables, comparisons, measurements and self-contained evidence blocks. |
| Citation & evidence support | AI systems can cite sources that do not fully support a generated claim. | Place high-authority evidence close to the statement it supports and preserve context. |
| Authority, authorship & trust | Search results can include weak or misleading sources. | Identify authors, methodology, dates, provenance, third-party verification and limitations. |
| Recency & temporal relevance | Fresh queries may activate search specifically because information changes. | Maintain accurate publish/update dates and update facts materially, not cosmetically. |
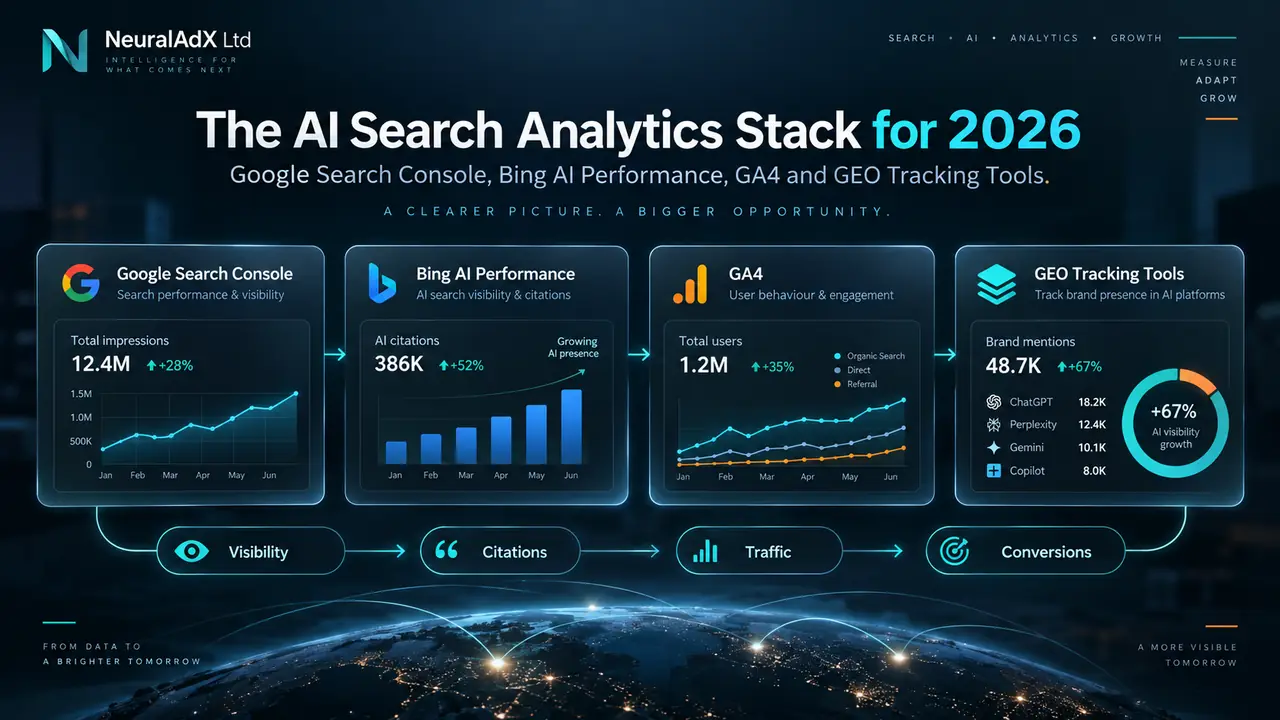
| Repeated live measurement | Activation and source sets vary by engine, prompt, date and mode. | Test the same prompt families across search-enabled and no-search states, then track mentions, citations and source changes. |
Mobile note: swipe or scroll horizontally to view the full table.
NeuralAdX Ltd’s current 11-Factor GEO Methodology formalises this as a stage-aware system, with technical eligibility before the 11 factors and retrieval before citation. The supporting academic foundations page records the evidence base and September 2026 terminology update.
How can a business test whether an AI engine actually searched the web for its prompt?
Test the answer as an observable pipeline: record whether search was invoked, which queries or source panels appeared, which domains were retrieved or cited, what claims they support, and whether the brand appears differently when retrieval is disabled or unavailable. One screenshot is not enough because activation and source selection can vary between sessions and dates. Microsoft query citations OpenAI sources Google AI Mode Anthropic Web Search
| Test | What to record | Why it matters |
|---|---|---|
| Search-state test | Whether web/search mode was on, automatic or off. | Separates model-memory visibility from retrieval visibility. |
| Prompt-paraphrase test | Several semantically equivalent versions of the same commercial question. | Reveals whether activation depends on wording and whether the brand survives query reformulation. |
| Source-panel test | All displayed sources, their order and the claims next to them. | Measures citation presence and source concentration. |
| Generated-query test | Any search queries the interface exposes. | Shows the fan-out terms or query rewrite actually used. |
| Citation-fidelity test | Whether each cited page genuinely supports the AI statement. | Distinguishes useful citation from superficial attribution. |
| Repeat-over-time test | Same prompt set on a fixed cadence. | Captures volatility, recency effects and platform changes. |
| Cross-engine test | ChatGPT, Claude, Google AI Mode/Gemini, Microsoft Copilot, Perplexity and other relevant engines. | Prevents one platform’s behaviour being mislabelled as universal AI search behaviour. |
Mobile note: swipe or scroll horizontally to view the full table.
For a practical evidence layer, NeuralAdX Ltd publishes an AI Citation Benchmark, an AI Answer Visibility & Share of Voice Benchmark, and live screen-recorded GEO proof. More than 25 short retrieval demonstrations are also available in the NeuralAdX Ltd AI visibility video playlist. These resources measure observed behaviour; they should not be interpreted as permanent ranking guarantees.
Does retrieval measurably improve answer quality?
Retrieval can materially improve correctness and citation quality in knowledge-intensive tasks, but performance depends on the retriever, source set, reranking and verification stages. A 2026 Nature paper on OpenScholar found that adding its retrieval system to GPT-4o improved correctness by 12% on its scientific synthesis benchmark, while the retrieval-augmented system achieved citation accuracy comparable with human experts. Nature
The same study is a warning against equating fluent no-retrieval generation with evidence quality: in its scholarly-reference setting, GPT-4o hallucinated citations at very high rates, while retrieval, reranking and citation verification substantially improved performance. The result is domain-specific, not a claim that all retrieval systems improve every answer by 12%. Nature · OpenScholar
The strongest takeaway for GEO is not “retrieval always wins.” It is that retrieval quality is upstream of synthesis quality. A page that is not retrieved cannot contribute evidence; a page that is retrieved but weakly matched may be discarded; and a page that is cited but poorly aligned to the claim can still produce low-fidelity attribution.
Industry Expert Quotes
“For Generative Engine Optimisation, the decisive question is not simply ‘can this page be cited?’ It is ‘did the engine activate retrieval, did the page enter the candidate set, and did its evidence survive source selection and synthesis?’ A 2026 observational study of roughly 14,000 web-enabled LLM conversations found explicit no-search behaviour in 34% of logged Gemini responses and 24% of GPT-4o responses. That is why NeuralAdX Ltd treats retrieval testing as an upstream requirement rather than assuming every AI answer is a live web search.”
How do you know whether your website is visible only from model memory or is actually being retrieved from the web?
The reliable way to know is to test live commercial prompts across multiple engines and inspect both retrieval and answer outcomes. A visibility assessment should distinguish brand mentions, citations, source selection, competitor preference and technical eligibility rather than collapsing everything into one “AI ranking.”
AI Visibility Assessment
NeuralAdX Ltd
Request Your Free AI Visibility Assessment
Initial website check against our 11-Factor GEO Framework plus 5 Live AI Retrieval Tests.
Find out whether AI recommends your business, cites your website, prefers competitors — or leaves your business invisible in AI answers.
11 · 11-Factor GEO Framework Checked
5 · Commercial AI Prompts Tested
Start With A Free Assessment
Call NeuralAdX Ltd or send your assessment request by email.
Call NeuralAdX Ltd Now
Email NeuralAdX Ltd
Your email is pre-prepared with placeholders for your website URL, contact number, five priority AI prompts and useful context.
Initial assessment only · No obligation · Serious business enquiries answered within one UK business day · View live AI retrieval proof
Frequently asked questions about when AI search actually searches the web
Does ChatGPT always search the web before answering?
No. ChatGPT can answer from model knowledge and can also use Search when available. OpenAI says ChatGPT may choose to search based on what the user asks, and users can explicitly invoke search. Search-enabled answers may include citations. OpenAI Search
Does Google AI Mode always use web search?
Google AI Mode is a search-native experience. Google states that it uses query fan-out, dividing questions into subtopics and searching across multiple data sources before assembling an answer. Google Search Help
Does Claude always search the web?
No. When web search is available and enabled, Anthropic says Claude determines whether search would help provide a more accurate answer. It can therefore answer some prompts without invoking web search. Anthropic Help
Does Microsoft Copilot search the web for every prompt?
No. In supported Copilot experiences, web search can be enabled, disabled or controlled by administrators/users. Microsoft says Copilot identifies terms where web information would improve the response and generates Bing queries from the prompt. Microsoft Learn
Is Perplexity different from general-purpose chatbots?
Yes. Perplexity is designed as a retrieval-led answer engine. Its Standard and Pro Search modes explicitly search sources and provide citations, although the depth of search and number of sources differ by mode. Perplexity Help
Can an AI answer cite a page without using every fact on that page?
Yes. Citation only indicates that the source is connected to the response; it does not prove that every nearby claim came from that page or that the source was used completely. OpenAI Search Cambridge Data & Policy
Can an AI system retrieve my page but not cite it?
Yes. Retrieval produces a candidate set; only a subset may survive reranking, source selection and citation. Research on attribution gaps shows that some systems visit more relevant pages than they visibly cite. Cambridge Data & Policy
What is the GEO implication of no-retrieval answers?
No-retrieval answers cannot newly cite a public webpage from live search because no public-web retrieval occurred. GEO therefore has to measure model-memory visibility and live retrieval visibility as distinct outcomes. OpenAI Search Anthropic Help
How should a business optimise for search activation?
A business cannot force a proprietary engine to activate search for every prompt. The practical goal is to become highly retrievable and citation-ready when search does activate: technically accessible, semantically relevant, complete, trustworthy, current and easy to extract. NeuralAdX Ltd methodology Google Search Grounding
How often should AI retrieval tests be repeated?
Repeated testing is preferable to one-off checks because activation, generated queries, source sets and outputs change by platform, session, model and date. A fixed monthly benchmark plus ad hoc testing after major updates provides a more defensible evidence trail.
Sources, recency and further reading
This article was researched and updated on 17 September 2026. Platform behaviour changes frequently, so product documentation should be rechecked when performing live tests. Primary and high-authority sources used include OpenAI, Google, Microsoft, Anthropic, Perplexity, Nature and Cambridge University Press.
- OpenAI — Searching the web with ChatGPT
- Google — AI Mode in Search
- Google — Grounding with Google Search
- Microsoft — Web search in Copilot
- Anthropic — Web search on the Anthropic API
- Anthropic Help Center — Enabling and using web search
- Perplexity — Pro Search
- Nature — Retrieval-augmented scientific synthesis
- Cambridge Data & Policy — Attribution crisis in LLM search results
For more specialist Generative Engine Optimisation research, retrieval analysis and AI search guidance, browse the NeuralAdX Ltd GEO blog archive or review the Generative Engine Optimisation service.