NeuralAdX Ltd editorial research · Reviewed 26 October 2026
What GEO can and cannot influence in model knowledge and live search results
This guide separates learned model knowledge, real-time web retrieval, conversation history and personal memory to explain how each affects AI citations, brand visibility and the limits of Generative Engine Optimisation.
Website optimisation can strengthen discoverable, verifiable source material, but cannot directly rewrite a third-party AI model’s weights or guarantee selection. Test live retrieval separately from learned knowledge, capture citations and brand mentions independently, and audit factual fidelity.
What is the difference between model memory and live web retrieval?
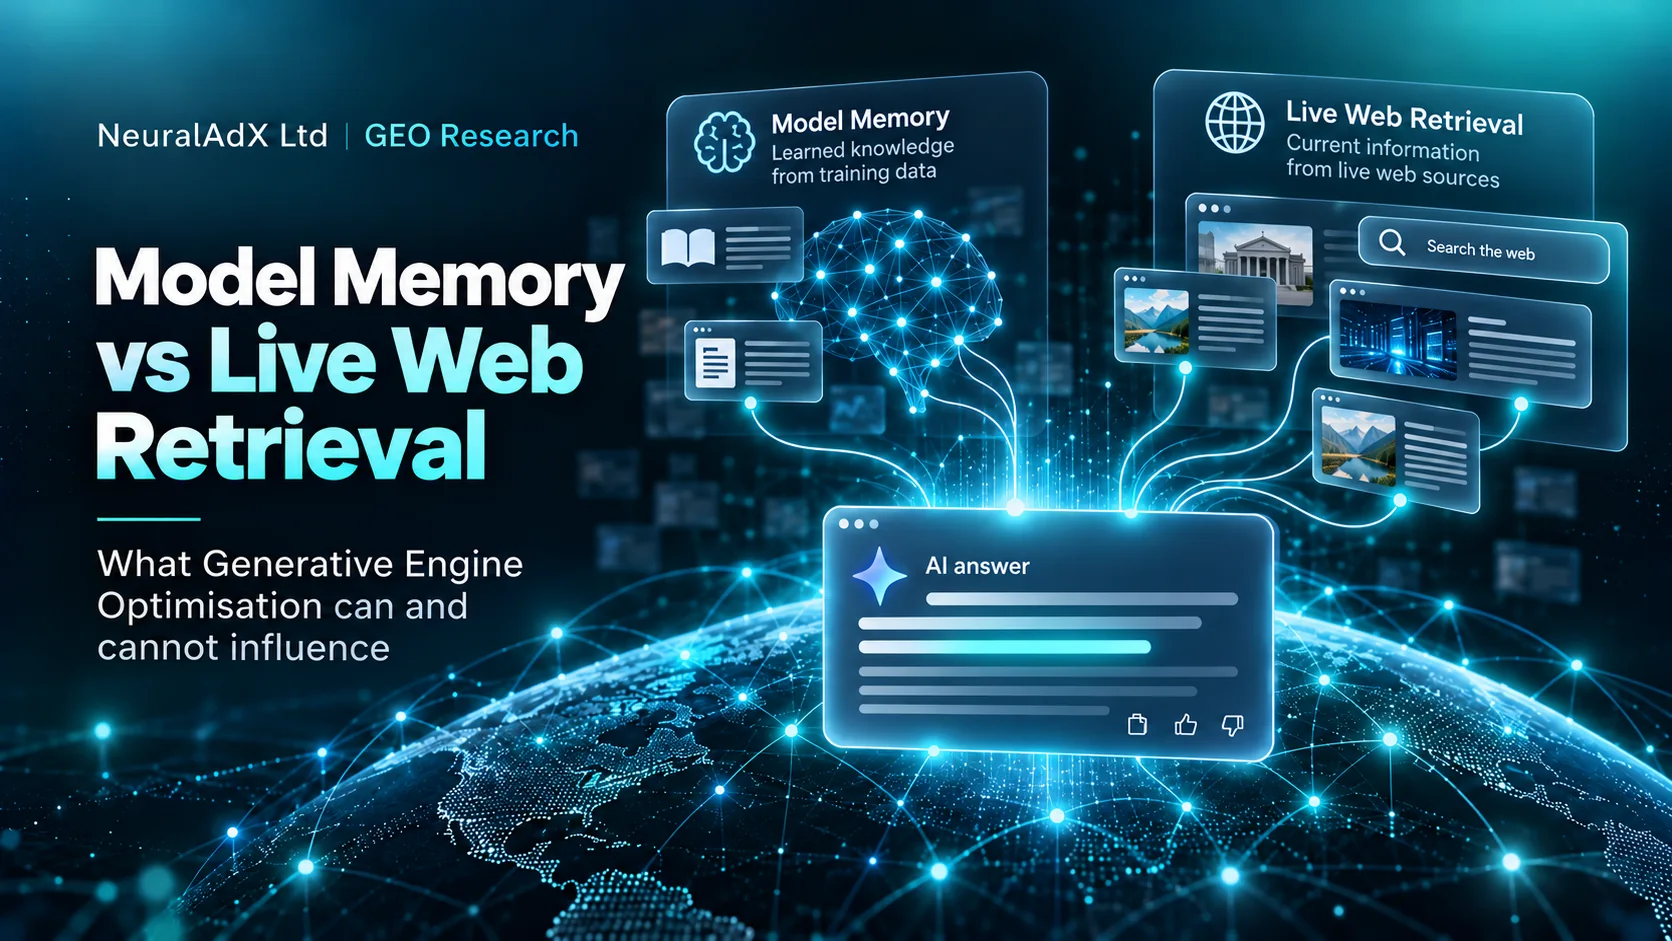
Model memory, in this context, means factual patterns encoded in an AI model’s trained parameters. Live web retrieval means the system obtains external pages or search results during the answer process. Model memory can help interpret and synthesise a question without looking up current sources; retrieval can bring in fresher, attributable evidence. A third concept, personal conversational memory, is a product feature and is not identical to either.
Generative Engine Optimisation (GEO) can improve the quality, structure, accessibility and independent verification of webpages eligible for retrieval. It cannot directly rewrite the weights of a deployed third-party model or force that model to retrieve, mention, cite or recommend a business.
Meta / NeurIPS 2020 RAG paperOpenAI on model limitationsWhat kinds of memory and evidence should a GEO audit distinguish?
On mobile, swipe horizontally to view all columns.
| Mechanism | What it stores or uses | Can ordinary site edits change it immediately? | Visible citation possible? |
|---|---|---|---|
| Parametric model knowledge | Patterns and facts learned during training | No direct immediate control | Not necessarily |
| Live web search | Current fetched pages, snippets and links | Potentially, once crawled and selected | Often, depending on interface |
| Retrieved internal documents | Knowledge bases or connected files available to authorised systems | Only within those retrieval systems | Depending on configuration |
| Conversation context | Prior messages in current conversation | User conversation, not website alone | Not intrinsically |
| Personal memory feature | Saved context/preferences when enabled | Account/product controlled | Not the same as web citations |
A response can mix prior model knowledge with retrieved evidence. A citation displayed alongside an answer does not prove every adjacent statement came from that link.
How do AI systems combine learned knowledge with retrieved sources?
The foundational retrieval-augmented generation paper by Lewis and colleagues introduced architectures combining parametric knowledge with non-parametric retrieval. Its experiments found more specific and factual generation than a parametric-only baseline on the studied tasks. This is a model-design finding—not evidence that every consumer AI search product uses that exact architecture.
Lewis et al., NeurIPS 2020In deployed AI search, a tool or system may reformulate a user’s question, search for candidate pages, select useful passages and synthesise an answer. The resulting text can still contain errors, omissions or unsupported citations.
How do ChatGPT Search, Google AI Mode and Microsoft Copilot handle retrieval?
OpenAI explains that ChatGPT Search may rewrite queries for search providers, review results and issue additional searches. Citations and Sources controls help readers inspect external evidence. Google documents query fan-out in AI Overviews and AI Mode, which may issue multiple related searches across subtopics. Microsoft explains that eligible Copilot web search generates a shorter Bing query from the user’s prompt, then uses returned information to compose a response.
OpenAI ChatGPT SearchGoogle AI featuresMicrosoft Copilot web groundingOn mobile, swipe horizontally to view all columns.
| System | Documented retrieval behaviour | What is not guaranteed |
|---|---|---|
| ChatGPT Search | Targeted queries and source citations when search used | Search on every turn or inclusion of any webpage |
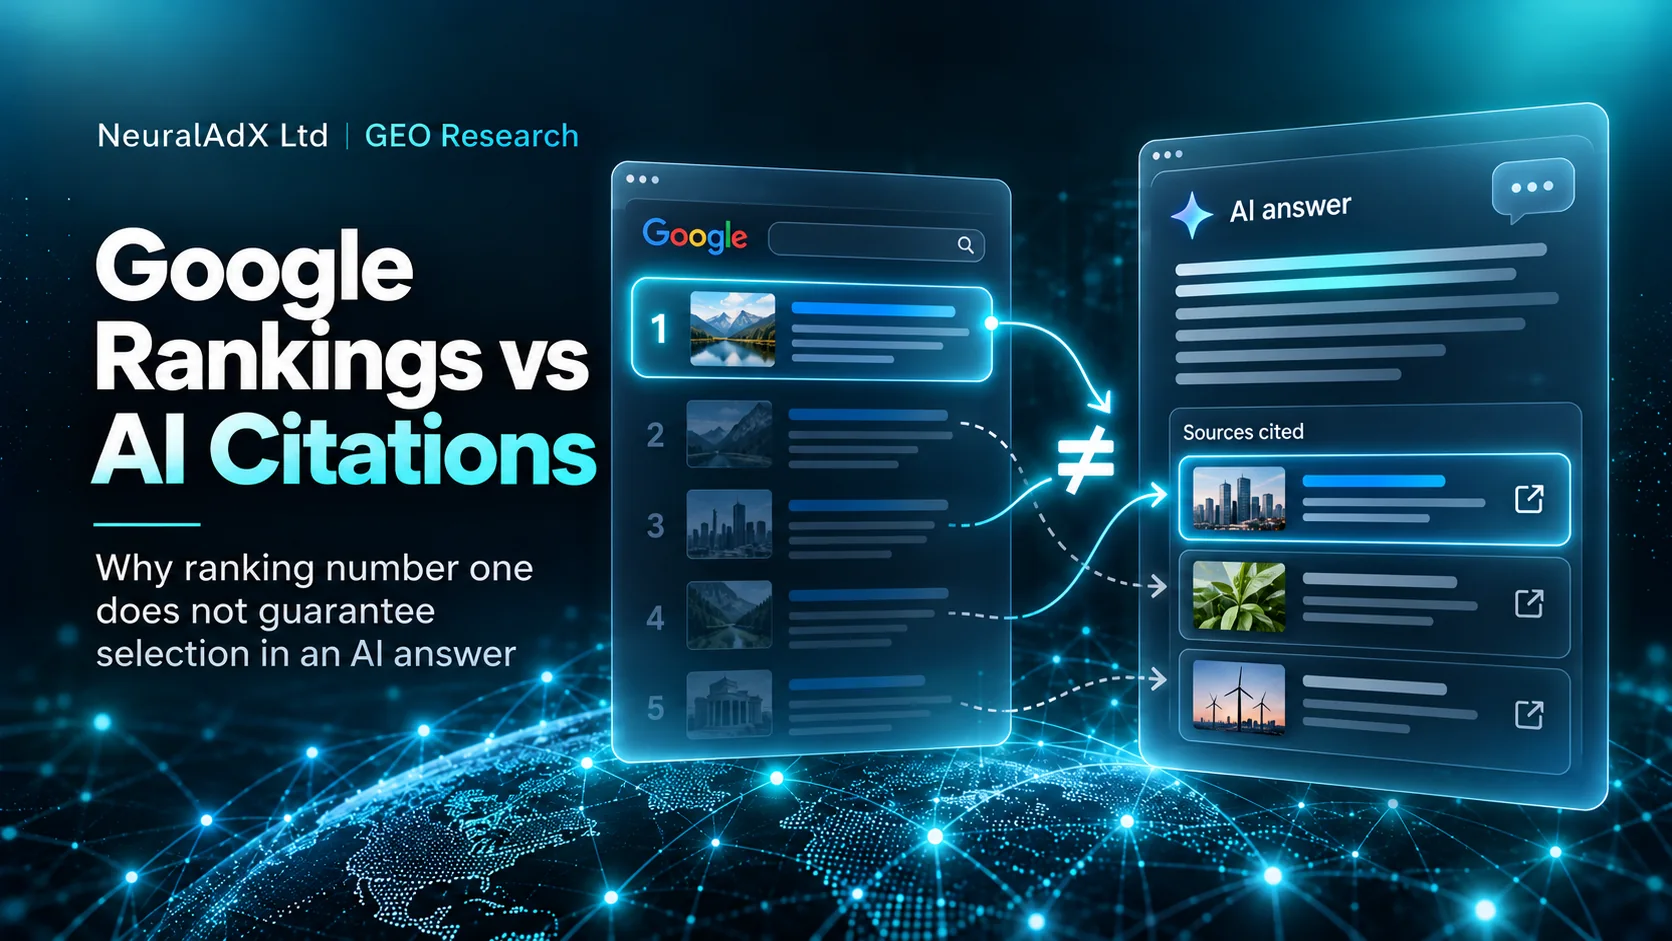
| Google AI Overviews / AI Mode | Query fan-out and supporting links | Citation of a top-ranking eligible page |
| Microsoft Copilot web grounding | Generated Bing search queries | Identical search process across all Copilot experiences |
What can Generative Engine Optimisation actually influence?
GEO can help pages become usable evidence: accessible relevant text, accurate entities, original statistics, dated sources, schema faithful to visible content, independent corroboration and internal links leading to fuller supporting explanations. These improvements may increase the opportunity to be discovered and selected, but no publisher controls the final retrieval and synthesis decision.
An update made today cannot reliably be assumed to have changed pre-trained model knowledge tomorrow. Any observed near-term change should first be tested as live retrieval, indexing, caching, conversation variation or other surface-specific effects.
Google technical eligibilityHow do you tell whether an answer relies on memory or current web evidence?
Treat this as a testable classification, not a certainty about private model internals. Ask the same exact question in a documented no-search mode where available and in a documented web-enabled mode; record visible citation links, query timestamps, source dates and whether the answer includes verified recent developments. A citation suggests visible retrieval support, but its absence does not prove that no hidden retrieval occurred.
On mobile, swipe horizontally to view all columns.
| Observed signal | Reasonable interpretation | Unsafe conclusion |
|---|---|---|
| Current dated citation | Some linked external evidence is presented | Every claim was retrieved |
| No visible links | No citations exposed in this response | Entire answer is necessarily parametric |
| Answer changes after web-enabled prompt | Search or mode may matter | Site edit caused the change |
| Repeated correct brand mention | Brand appears under those tests | Model weights encode a verified fact |
How should a controlled GEO memory-versus-retrieval experiment be designed?
Create matched prompt families covering definitions, current facts, company comparisons and transactional questions. Test each with the same language, location and constraints, save full answers and sources, and repeat the panel over dates. Separate the intervention date from crawl and re-indexing observations.
On mobile, swipe horizontally to view all columns.
| Step | Evidence to capture |
|---|---|
| 1. Baseline | Prompts, platform, account, mode and date |
| 2. Mode comparison | Search-disabled versus search-enabled if available |
| 3. Source audit | Exact cited URL, claim, original publication date |
| 4. Site changes | Content edit, crawl access, caching state and time |
| 5. Recheck | Repeated prompt outputs at matched intervals |
| 6. Classification | Named, cited, recommended, supported or unverified |
Illustrative workload: 5 prompt families × 4 AI systems × 3 repetitions × 2 mode conditions = 120 observations, only where a comparable mode control exists. This is planning arithmetic rather than an industry-valid sampling threshold.
Which results matter more than an unsupported memory-versus-retrieval claim?
Measure visible citation rate, brand mention rate, recommendation suitability, factual fidelity and freshness separately. State denominators clearly. Do not use a static citation score to claim access to the internal parameter weights of ChatGPT, Google or another system.
On mobile, swipe horizontally to view all columns.
| Metric | Operational calculation | Main limitation |
|---|---|---|
| Owned-source citation rate | Eligible answers linking to owned source ÷ eligible answers | Displayed sources only |
| Brand mention rate | Answers naming brand ÷ eligible answers | Not proof of citation |
| Correctness rate | Verified supported answer claims ÷ checked claims | Depends on audit protocol |
| Freshness | Answer references evidence newer than a cutoff | May mix learned and retrieved facts |
| Consistency | Same outcome across repeated runs ÷ total repeats | Not permanent inclusion |
What can charts reveal about observed retrieval without pretending to see model weights?
The following illustrative table and diagrams show 20 hypothetical answer observations, divided by visible evidence status. These are not NeuralAdX Ltd benchmark results or platform population statistics.
On mobile, swipe horizontally to view all columns.
| Visible outcome | Hypothetical answers | Share |
|---|---|---|
| Cites at least one checked relevant source | 11 | 55% |
| Contains citations but source support unverified | 5 | 25% |
| No citations displayed | 4 | 20% |
Checked sources55%
Unchecked citations25%
No visible citation20%
■ Cyan: checked relevant citations · ■ Blue: unverified citations · ■ Purple: none displayed. These are illustrative values; absence of citation is not a model-memory measurement. On mobile, scroll if needed.
What does primary research establish about retrieval and answer factuality?
The NeurIPS 2020 retrieval-augmented generation paper combined learned model parameters and an external document index, reporting improvements on several knowledge-intensive tasks relative to the studied parametric-only baseline. Google’s 2024 FACTS Grounding benchmark was designed to evaluate whether model responses correctly use provided source material. Both reinforce a key distinction: having access to sources and faithfully answering from them are separate questions.
NeurIPS 2020Google DeepMind FACTS Grounding 2024OpenAI’s own documentation warns that confident language is not a measure of correctness and that cited sources may be incomplete, outdated or incorrect. That is why the GEO audit must validate individual claims, not merely count source links.
OpenAI on accuracyIndustry Expert Quotes
Proposed original commentary for the author’s approval: “At NeuralAdX Ltd we distinguish what an AI system can already explain from what it visibly retrieves to support a current answer. Improving a webpage does not directly rewrite a third-party model’s training weights; the measurable near-term question is whether our content becomes accessible, selected, cited and accurately represented when web retrieval is used.” — Paul Rowe, Founder, Chief Generative Engine Optimisation Officer & CEO.
This is newly drafted suggested commentary, not a verified previous quotation, and requires author approval.
Where can readers examine NeuralAdX Ltd’s related GEO methods and evidence?
The 11-Factor GEO Methodology explains the citation, authority, recency and source-diversity approach. The GEO explainer outlines basic terminology; the Generative Engine Optimisation service describes applied work.
Compare the AI Citation Benchmark with the AI Answer Visibility and Share of Voice Benchmark. Further context includes third-party mentions and verification, AI retrieval video demonstrations and the GEO editorial archive. These links are explanatory, not a CTA.
Frequently asked questions
Does ChatGPT always search the live web?
No. Search depends on the product, mode and task. Confirm whether web search was used rather than inferring it from the model’s confidence.
Can editing my website change an AI model’s trained memory immediately?
No. A page update cannot directly modify a deployed third-party model’s learned weights; effects on web retrieval are a different matter.
Can an AI answer use model knowledge and live results together?
Yes. A system can synthesise retrieved evidence using knowledge and capabilities learned during training.
Does a citation prove that the answer is correct?
No. Check the precise claim against the linked source, including scope and date.
How is personal memory different from model memory?
Personal memory is a configurable product feature for retaining relevant user context; parametric knowledge refers to patterns encoded during training.
Does Google indexing guarantee an AI Mode citation?
No. Indexing and snippet eligibility are necessary conditions for supporting links but do not guarantee inclusion.